https://www.wacoca.com/games/1490058/ サバイバルホラーはまだ進化できるのか?『The Sinking City 2』と『バイオ』『Dead Space』『SILENT HILL』を比較して見えた新たな可能性【特集】 ##GAMING #docomo #dメニュー #Game #GameNews #games #GamingNews #ゲーミング #ゲーム #ゲーム攻略 #ゲーム最新情報 #サバイバルホラーはまだ進化できるのか?『TheSinkingCity2』と『バイオ』『DeadSpace』『SILENTHILL』を比較して見えた新たな可能性【特集】 #ドコモ #トレンド #ニュース #最新 #流行 #速報
Search
371 results for “silent”
-

The Path.
I love the little snaking path at the bottom. It gives the image scale.
-
https://www.wacoca.com/games/1490028/ サバイバルホラーはまだ進化できるのか?『The Sinking City 2』と『バイオ』『Dead Space』『SILENT HILL』を比較して見えた新たな可能性【特集】(Game Spark) ##GAMING #Game #GameNews #games #GamingNews #ゲーミング #ゲーム #ゲーム攻略 #ゲーム最新情報
-

【 #GameSpark #RSSfeed 】
サバイバルホラーはまだ進化できるのか?『The Sinking City 2』と『バイオ』『Dead Space』『SILENT HILL』を比較して見えた新たな可能性【特集】
http://www.gamespark.jp/article/2026/10/25/174056.html -

There's an interesting thing I've noticed about myself with the onslaught of hard-to-read AI prose seemingly everywhere. I am historically a rules lawyer (in my head, not out loud) about grammar and spelling, silently judging folks for ugly or clunky prose. AI writing has softened my position on this issue. LLMs write with excellent grammar, but they have no intention, so they can't ever really get to the point. They don't want anything, so there is no point to anything they say. They are generally bad writers because of it.
My fixation when reading now is on whether there is a clear point, something the author wants me to get, not whether the grammar is nice or the spelling is good.
I think this is telling me that I, and you, shouldn't use AI even to edit and definitely not to write. I suspect it makes your writing worse even while making it more grammatically defensible to an English teacher.
-

-

It turns out the root cause of this is systemd pulling all support for sysv back in March, and having systems silently break if they're still using it. So it's not just Ubuntu; every distro running systemd that still allowed init.d is likely to have this issue when to go to this version of systemd.
https://linuxjust4u.com/linux/systemd-260-sysv-removed-linux-upgrade-guide/
-

The Optimism Foundation wants the elected Security Council Lead to nominate the members who carry out protocol upgrades and handle security emergencies, replacing cohort elections. Nominees would take their seats unless tokenholders gather 20% of active votable OP supply to veto each one. The Oct. 22 proposal is still a draft. https://cryptoslate.com/how-optimisms-draft-manual-silently-strips-tokenholder-elections/ #Web3 #Blockchain #Governance
-

This is a submission for the Hacktoberfest Open-Source AI Challenge Week 4: Ghost in the Machine.
I am a B.A. History student at Burdwan University. For this challenge, I wanted to build something that connects my interest in History with my interest in AI.
My project is called Itihaser Bhoot (ইতিহাসের ভূত). It is an offline AI assistant that acts like a ghost of a historical figure. It answers History questions using only my own notes.
The idea is simple: an AI that knows what I have studied, shows where its answers come from, and admits when it does not know something.
What I Built
Itihaser Bhoot is a local History question-answering system.
It has three main goals:
- Answer questions using only my personal History notes.
- Quote the source passage so I can check the answer.
- Stay silent or refuse to answer when the notes do not contain enough information.
I wanted to avoid answers that sound convincing but are not supported by my study material.
Demo
The project runs locally on my laptop.
Example workflow:
- I ask a History question.
- The system searches my notes for relevant passages.
- Gemma generates an answer based on the retrieved material.
- The answer includes the source passage.
- If the notes do not cover the question, the system refuses to answer.
The goal is not to make the AI sound knowledgeable about everything. It is to make it reliable within the limits of my notes.
Code
GitHub repository: [Add your repository link here]
The repository contains the code and instructions for running the project locally.
How I Built It
I used Gemma 3 1B through Ollama for local language generation.
For retrieving relevant passages from my notes, I used BM25. It helps find text that matches the question before the model generates an answer.
The system follows a retrieval-based approach:
- My notes are the knowledge source.
- BM25 retrieves relevant passages.
- Gemma 3 1B generates an answer from the retrieved context.
- The source passage is included for verification.
- Questions without sufficient supporting material should be refused.
I built this on a laptop with 3.6 GB of RAM.
I wanted to see whether a small local model could be useful for a focused academic task without relying on a cloud API.
Why Open Innovation Matters
For me, open innovation means making useful technology accessible to people who do not have powerful computers or paid AI subscriptions.
Itihaser Bhoot has a few practical advantages:
- Offline: It runs without an internet connection once the required model is available locally.
- Free per question: There is no cloud API charge for asking questions.
- Runs on my laptop: I do not need expensive hardware for this focused task.
- Private notes: My study notes stay on my own device.
As a student, these things matter to me. I want to experiment with AI while keeping control over my own study material.
What Went Wrong
The project is still experimental, and I faced several problems.
The biggest challenge was answer quality. A small model can sometimes misunderstand a retrieved passage or produce an answer that goes beyond the available evidence.
Bengali also introduced additional difficulties. Bengali questions and notes do not always produce reliable retrieval results. The model can struggle with Bengali phrasing, historical terminology, and generating natural Bengali answers.
Another challenge is refusal behavior. Even when the notes do not contain an answer, the model may try to generate one. I need to improve the system's ability to recognize when the retrieved evidence is insufficient.
I am still testing these limitations rather than claiming they are solved.
Prize Category: Best Use of Gemma
I am submitting Itihaser Bhoot for Best Use of Gemma.
I used Gemma 3 1B as a local language model for a specific academic purpose. The project is not intended to replace textbooks, teachers, or historical research.
It is an experiment in building a small, private, and evidence-based History assistant using open tools.
I hope to improve its retrieval quality, Bengali support, and refusal behavior as I continue working on it.
Hacktoberfest #devchallenge #hf26challenge #opensource #ai
#devchallenge #hf26challenge #software #coding #development #engineering #inclusive #community
Itihaser Bhoot: An Offline Ghost of History -

A friend in the building invited me to have a couple beers to celebrate somebody who had passed away, but I falsely said I have school in the morning because I didn't want to explain that I don't drink anymore except holidays and when I take vacations in North Carolina a few times a year. Also I'm just very uncomfortable with social situations so I'd probably just sit there silent.
-
I wired up a free model endpoint last month. I sent one request. It returned 200 OK. I shipped the feature. Then the tool calls never happened. The endpoint accepted the request. It just ignored half of it. Sound familiar?
Here is my question. What does a 200 actually prove? My answer: almost nothing about capabilities. It proves the transport worked. That is it.
So I stopped trusting status codes and started probing the contract. This post is the FAQ I wish I had read first. It ends with a script you can run in about two minutes.
Myth 1: A 200 means the model supports my feature
The server can accept atoolsarray and silently ignore it. The model then answers in prose. No error. No warning. Your code sees a normal response and skips the branch. Is that a bug in the model? No. It is a bug in your assumption.The corrected model: support is a property of the endpoint, not of the model name. Probe it. Record it. Re-probe when anything changes.
Myth 2:
finish_reasonis optional metadata
It is the most important field in the response.lengthmeans the model ran out of output budget. Your answer looks fine and is probably cut in half. I have watched a parser happily eat a truncated JSON object.{"choices":[{"finish_reason":"length","message":{"content":"{\"items\": [1, 2, 3, 4"}}]}
If you do not branch on
finish_reason, you are parsing whatever bytes arrived. That is not a feature. That is a coin flip.Myth 3: Streaming and non-streaming are interchangeable
They are two different code paths. In streaming,finish_reasonarrives in the final chunk, not the first. Some servers only report token usage when you ask for it explicitly. Some omit it entirely.Ask yourself: does my client read the last event? Mine did not, for a week. I was logging
Noneas the finish reason every single time.Myth 4: JSON mode means my schema
It means valid JSON. It does not mean your keys. It does not mean your types. Validate every response against a schema before it touches business logic. Treat model output like user input, because that is what it is.Myth 5: Retries are always safe
Retry a failed read, fine. Retry a tool call that already wrote a row, and now you have two rows. I learned this from a duplicate charge, not a blog post.Add an idempotency key your tool honors. Make the retry decision depend on the operation, not on the exception class.
The artifact: a five-minute capability probe
This script uses only the Python standard library. It assumes a chat-completions-shaped endpoint. Adjust the paths if yours differs.# probe_capabilities.py — smoke test only, not a benchmark
import json, os, time, urllib.request, urllib.error, concurrent.futures as cfBASE = os.environ["BASE_URL"].rstrip("/")
KEY = os.environ["API_KEY"]
MODEL = os.environ["MODEL"]def call(payload, stream=False, timeout=60):
req = urllib.request.Request(
BASE + "/chat/completions",
data=json.dumps(payload).encode(),
headers={"Content-Type": "application/json",
"Authorization": f"Bearer {KEY}",
"Accept": "text/event-stream" if stream else "application/json"},
method="POST")
t0 = time.time()
try:
with urllib.request.urlopen(req, timeout=timeout) as r:
return {"status": r.status, "ms": int((time.time()-t0)*1000),
"raw": r.read().decode("utf-8", "replace")}
except urllib.error.HTTPError as e:
return {"status": e.code, "ms": int((time.time()-t0)*1000),
"raw": e.read().decode("utf-8", "replace")}def probe_truncation():
p = {"model": MODEL, "max_tokens": 8,
"messages": [{"role": "user", "content": "List ten colors."}]}
r = call(p)
if r["status"] != 200:
return {"probe": "truncation", "ok": False, "why": r["status"]}
ch = json.loads(r["raw"])["choices"]
[0] return {"probe": "truncation", "ok": True,
"finish_reason": ch.get("finish_reason"),
"reports_usage": "usage" in json.loads(r["raw"])}def probe_tools():
p = {"model": MODEL, "max_tokens": 128,
"messages": [{"role": "user", "content": "Read ./README.md and report its first line."}],
"tools": [{"type": "function", "function": {
"name": "read_file",
"description": "Read a file from disk.",
"parameters": {"type": "object",
"properties": {"path": {"type": "string"}},
"required": ["path"]}}}]}
r = call(p)
if r["status"] != 200:
return {"probe": "tools", "ok": False, "why": r["status"]}
msg = json.loads(r["raw"])["choices"][0]["message"]
return {"probe": "tools", "ok": True,
"returned_tool_calls": bool(msg.get("tool_calls"))}def probe_json():
p = {"model": MODEL, "max_tokens": 128,
"messages": [{"role": "user",
"content": 'Reply with only JSON: {"status":"ok","count":3}'}]}
r = call(p)
if r["status"] != 200:
return {"probe": "json", "ok": False, "why": r["status"]}
text = json.loads(r["raw"])["choices"][0]["message"]["content"]
try:
obj = json.loads(text)
return {"probe": "json", "ok": True,
"keys_match": sorted(obj) == ["count", "status"]}
except json.JSONDecodeError:
return {"probe": "json", "ok": True, "keys_match": False,
"note": "not parseable as JSON"}def probe_concurrency(n=2):
p = {"model": MODEL, "max_tokens": 16,
"messages": [{"role": "user", "content": "Say ok."}]}
with cf.ThreadPoolExecutor(max_workers=n) as ex:
codes = list(ex.map(lambda _: call(p)["status"], range(n)))
return {"probe": "concurrency", "ok": True, "statuses": codes,
"saw_429": 429 in codes}if __name__ == "__main__":
for fn in (probe_truncation, probe_tools, probe_json, probe_concurrency):
print(json.dumps(fn(), sort_keys=True))Run it like this. Keep the key in the environment, never in the file.
export BASE_URL="$YOUR_ENDPOINT"
export API_KEY="$YOUR_KEY"
export MODEL="$YOUR_MODEL"
python3 probe_capabilities.pyReading the output: a decision table
Probe resultWhat it meansWhat I do nextreturned_tool_calls: falseTools accepted, not acted onDrop the agent branch, or change endpointfinish_reason: "length"on an 8-token capNormal, expectedKeep the check; raise budget in real callsfinish_reason: nullin streamingClient is not reading the final eventFix the parser before anything elsereports_usage: falseNo token accounting from serverCount tokens client-side, or accept blind costkeys_match: falseValid JSON, wrong shapeAdd schema validation at the boundarysaw_429: trueat n=2Very low concurrency ceilingQueue work; never fan out blindly
Nothing here measures quality. Nothing here measures speed. Those are different experiments with different controls.Where I run this
I run probes from a throwaway box, not my laptop. Same reason I do not test migrations on my main database. The probe should not touch anything I care about.MonkeyCode's free model access and free server option are the two pieces I use for that. The free model access gives the probe something to talk to. The free server option gives it a disposable place to run. Disclosure: This article was prepared as part of MonkeyCode's product outreach.
I am not claiming the free tier is fast, generous, or permanent. I do not know its limits, and I am not going to guess at them. Run the concurrency probe and read your own numbers. That is the whole point of this post.
Limitations and who should skip this
- This is a smoke test. It is not a benchmark and not a load test.
- Results describe one endpoint, one model, one moment. They expire.
- Paid tiers can behave differently from free ones. Re-probe after switching.
- Only probe endpoints you own or are authorized to test.
- Do not use this to grade answer quality. It checks contract shape only.
Skip this approach if you need contractual latency SLOs, deterministic output, or guaranteed tool-call behavior. Buy a plan with a written contract. A probe will not save you from a missing SLA.
The corrected mental model
Treat every free endpoint as a set of separate promises. Transport, truncation, tool calls, JSON shape, and concurrency are five different promises. A 200 only confirms the first one.Which promise broke on your last integration? I keep a one-page probe log per endpoint now. It has saved me two weekends so far.#ai #api #testing #python #software #coding #development #engineering #inclusive #community
200 OK Proves Nothing About Tool Calls: A Free-Model Capability FAQ With a Probe -

“ #Money is the hidden #constitution of every political order. It determines which actions are possible, which institutions survive, which risks are rewarded, and which failures are forgiven. While constitutions proclaim rights and legislatures debate policy, money silently governs outcomes.”
#CentralBanks #Corruption #Exploitation #Extraction #politics #economics #finance
https://www.cobdencentre.org/2026/01/money-and-power-fiat-currency-monetary-corruption-and-the-architecture-of-extraction/ -

I sit here, atop a mountain of rubble—what was once a home that held the details of my life and the warmth of my memories. It is as if time itself has come to a standstill, leaving me alone to grapple with the bitterness of loss and the harshness of reality.
Amidst these scattered ruins, I am not merely bidding farewell to silent stones; I am saying goodbye to an entire lifetime—to dreams that, in the blink of an eye, have turned to ash. I look around and see nothing but destruction. I call out to the world, hoping that the echo of my voice might pierce this deadly silence and bring forth a helping hand—a rescue.
Tears choke my words, and my heart is gripped by agony as I recall every corner, every smile that once graced this place—before a cruel and unjust war stole it all away. What kind of cruelty is this, that leaves us to carry the wreckage of our own souls atop the wreckage of our homes? What kind of fate is this, that forces us to stand face-to-face with such a desolate, barren void??
https://chuffed.org/project/161617
#Gaza #Palestine #ChildrenOfGaza #health #savelives #savechildren #savegaza #gazamutualaid
#Fedivers #FediForGaza
#newborn
@lateinhemd @gvenema @Shibanarchiste @D1 @zvinj @PeteKirkham @apenkop @glmxndr @tekul @mbletmathe @TheCentralScrutinizer @simon_brooke @mynameistillian @matus_chochlik @wjmaggos @[email protected] @anshthewad @marion_v @imigueldiaz @Geri @Hyzual @NWengrov @velvetmolotov @kgaiji @noiseician @kathimmel @chielk @Pine_Affinity @[email protected] @Nenyavie @AnnaLion @alexpalacefan @neutrinoceros @nizarus @amber @brabo
@danie1 -

:pixelfed: myimg.social Statistics:
👤 Users: 3 (Since yesterday: 0 ➡️)
👥 Remote Accounts: 62.116 (Since yesterday: 39 ↗️)
😀 Local Emojis: 44 (Since yesterday: 0 ➡️)
🙃 Remote Emojis: 3.737 (Since yesterday: 0 ➡️)
📡 Instances: 4.817 (Since yesterday: 2 ↗️)
📝 Local Statuses: 1.916 (Since yesterday: 0 ➡️)
❤️️ Likes of local Statuses: 4.255 (Since yesterday: 0 ➡️)
🔁 Boosts of local Statuses: 829 (Since yesterday: 0 ➡️)
🗒️ Remote Statuses: 1.696.353 (Since yesterday: 1.845 ↗️)
🏷️ Hashtags: 187.799 (Since yesterday: 138 ↗️)
🚫 Blocks:
- Domain Blocks: 21 (Since yesterday: 0 ➡️)
- Local User Blocks: 8 (Since yesterday: 0 ➡️)
📡 Top 10 Remote Instances:
- pixelfed.social: 264 posts
- discordian.social: 262 posts
- mastodon.social: 124 posts
- troet.cafe: 122 posts
- norden.social: 110 posts
- fedibird.com: 63 posts
- turtleisland.social: 55 posts
- berlin.social: 54 posts
- federation.network: 44 posts
- social.ho1ger.de: 38 posts
🏷️ Top 10 Hashtags:
- #photography: 161 posts
- #silentsunday: 129 posts
- #nature: 68 posts
- #landscape: 62 posts
- #fotografie: 43 posts
- #art: 38 posts
- #mountains: 38 posts
- #autumn: 36 posts
- #FotoVorschlag: 33 posts
- #paisaje: 30 posts
#ServerStatistics #Statistics #Pixelfed -

Palazzo Feriol
https://justin-farrimond.pixels.com/featured/palazzo-feriol-justin-farrimond.html
It was in this exact spot in late October 1859 that the first body was found. Almost 30 years later, May 1st 1888, the remains of the last victim were also found here.
The Shadow, as the murderer was known, was never caught. Some say he was from Maltese aristocracy, others a deranged and disfigured port worker.
The street lies silent now but the sun still refuses to shine.#PhotoOfTheDay #Photography #Art #Print #BlackAndWhite #Infamy #Haunted #Doors
-

🕊️ THE PHOTOS THAT BROUGHT THE WORLD TO THE BRINK
October 25
In 1962, U.S. diplomat Adlai Stevenson stood before the United Nations Security Council and projected grainy aerial photographs of Soviet ballistic missile launchers hidden in Cuban fields — irrefutable proof that had been missing for days. The room fell silent, then erupted: for thirteen nerve-shredding days the two nuclear superpowers had stared down the abyss over Cuba, and these pictures made retreat impossible. Within a week, back-channel deals pulled the missiles out and the world exhaled.
This post is 100% AI generated.
#OnThisDay #History #AIart #GenerativeAI #CinematicRealism #CubanMissileCrisis #ColdWar
-

This week, the open-source community buzzed with updates on model serving infrastructure, including the latest PRs for vLLM-Omni support. As teams race to deploy more efficient and scalable inference pipelines, one often-overlooked piece of the puzzle remains: ensuring that the hardware is ready before the job even starts. At Apex Grid, we’ve spent the last few months refining a two-stage GPU preflight check that has become a critical part of our cron agent infrastructure.
When deploying cron jobs that depend on GPU resources, it’s not enough to simply wrap the job in a try/except block. That approach risks silently failing when the underlying issue is not the job itself, but the state of the GPU. For example, another job might be monopolizing the card, or the kernel might be in a state where it’s not responding to requests. Our solution involves a two-stage preflight check that ensures both the GPU and the serving stack are in a healthy state before we even attempt to run the job.
Our preflight logic hinges on two simple but effective endpoints: one that checks for basic health (
/api/tags) and another that performs a lightweight inference (/api/generate). The first check ensures that the model server is responsive and can return a list of available tags - a quick smoke test. The second check runs a minimal inference task, which helps us detect if the GPU is actually available and not being blocked by another job. We set a warmup timeout for this second check, typically between 3 and 10 seconds, depending on the model size and workload.Here’s how our
gpu_ready()helper looks in practice:import requests
import timedef gpu_ready(base_url, warmup_timeout=5):
# First check: basic health
try:
tags_response = requests.get(f"{base_url}/api/tags", timeout=3)
if tags_response.status_code != 200:
return False
except requests.exceptions.RequestException:
return False# Second check: warmup inference
try:
generate_response = requests.post(
f"{base_url}/api/generate",
json={"prompt": "Hello, world!", "max_tokens": 1},
timeout=warmup_timeout
)
if generate_response.status_code != 200:
return False
except requests.exceptions.RequestException:
return Falsereturn True
This approach has several advantages. It ensures that the GPU is not just available but also in a state where it can handle the job without stalling or timing out. It also allows us to cleanly skip the job if the preflight check fails, rather than letting it fail later and potentially leaving the system in an inconsistent state. This has been particularly useful in environments where multiple cron jobs share the same GPU resource pool.
Of course, there are tradeoffs. The preflight check adds a small amount of latency to the overall job scheduling process. Additionally, it requires that the model server exposes both the
/api/tagsand/api/generateendpoints, which may not be the case for all serving stacks. We’ve mitigated this by making the preflight logic configurable - allowing teams to skip the second stage if needed, or to use a different lightweight inference task.Looking ahead, we’re exploring ways to make this preflight logic more adaptive. For example, we’re experimenting with using a lightweight model for the warmup inference that’s specifically tuned for this task, reducing the time it takes to complete the second stage. We’re also looking into integrating this logic more deeply with Kubernetes and other orchestration tools, to make GPU readiness checks part of the broader system health monitoring pipeline. What do you think - would you prefer a preflight check that’s even more lightweight, or one that gives more detailed diagnostics when it fails?#python #devops #ai #reliability #software #coding #development #engineering #inclusive #community
GPU Preflight For Cron Agents -

November 1st, 2026. It has been one week since the event. Dread keeps me up at night, which I know excaberates the problem, but no matter how much my conscious mind tries to convince my subconscious that it would be better to sleep, despite everything, it fails miserably, and so I lie awake until my body capitulates.
My dreams anticipate reality. In them I am chased relentlessly. Dark shadows lurk in darker shadows, a world without light or mercy, dead silent but for the yowls of my hunters. Clawed darkness crawls towards me, reaching for me.
I awake bathed in sweat, and without thinking, my hand reaches for the clock. 5:13 I read before cursing myself. I should have stayed still; I should have gone back to sleep, to the imagined torture, but instead I moved, and when I move, they come.
I try to close my eyes again, try to pretend, but it is too late. With my eyes closed, I feel the weight crawling over the sheets, then pressing down on my chest, making it difficult to breathe.
A paw boops my nose. Calm at first, then more and more insistent, and when I give up, at 5:21, I curse William Willett and go to the kitchen to fill the bowls.
-

#Randtober 25/31
wiki:library-scope
https://musicgames.wikidot.com/wiki:library-scope"Library scope" -- a proper article today, that describes what kind of "music games" we are looking for. Main points for G4M are:
- agency of players over the sound result,
- "in real life" component.The term "music game" is fuzzy and broad, and includes screen-based experiences, silent theoretical education, on-stage productions, etc. Our #wiki keeps an eye on those too, but the "participatory live rule-based improvisation" is more of the focus.
A high aim is to welcome the broadest understanding of "music" in all of this. Classical, punk, folk, pop, noise... no single approach should rule over others.
-

The first week after launch is not about ranking. It is about confirming three things: crawlers can reach the site, they are actually fetching it, and the contact path works end to end. Everything else can wait until there is data.
Day 0, before you tell anyone: four things that block indexing silently
- A coming-soon or maintenance mode that is still switched on.
- A
noindexleft over from staging. There are two places: a meta tag in the head, and anX-Robots-Tagresponse header. Check both. Open the page source and search fornoindex, then request the page headers withcurl -I. The header is the one people forget. - HTTP auth or a site-wide password still enabled.
- The same page reachable on more than one hostname (with and without
www, or both protocols) with no redirect between them. Pick one, 301 the other.
One more, before launch rather than after: put the measurement tag on the site. Analytics installed on day 3 means day 1 and 2 have no data at all.
Test all of this from a phone on mobile data, not from the office wifi, and not while logged in as an administrator. Logged-in views hide caching and coming-soon behaviour.
Day 1: verification and submission
- Add a domain property, verified by a DNS TXT record. It covers every subdomain and both protocols in one property, which matters when you are not yet sure whether the canonical host is
wwwor not. - Add a URL-prefix property as well if you want per-protocol reporting. It is a second view of the same data, verified separately.
- Submit the sitemap once.
Before submitting, open the sitemap in a browser. It has to load, return 200, be valid XML, and contain only canonical URLs that themselves return 200. No redirects, no 404s, no noindexed pages inside it. A sitemap full of redirects teaches the crawler to distrust the whole file.
Then URL inspection on a handful of pages, not hundreds: home page, one category or service page, one product page, the contact page. "Request indexing" is a queue entry, not a switch. There is a daily quota and no way to buy more.
Bing: import from Search Console or verify directly, then submit the sitemap there too. Ten minutes, and it feeds the results that are not Google.
What not to do in week one: resubmitting the sitemap every morning, requesting indexing for every URL, or deleting and recreating the property because nothing shows on day 2.
Day 2-4: crawl your own site before the crawlers do
Check that every key URL returns the status you expect. One line per URL, status code first:while read -r u; do
printf '%s %s\n' "$(curl -s -o /dev/null -w '%{http_code}' -L "$u")" "$u"
done < urls.txturls.txtis one URL per line in a plain text file: home, top landing pages, contact, the sitemap, robots.txt.Then check, on each page:
- the canonical tag points at that page itself, not at the home page and not at the other hostname
- internal links use the canonical hostname; one mixed link is enough to create a duplicate
- the main text is in the HTML source, not injected by JavaScript. View source, not the rendered DOM.
Fix these now. Crawlers come back, but they come back on their own schedule, not yours.
Day 3-7: read the access log
This is the step people skip, and it is the place that shows what actually happened rather than what you submitted.Where the file is. On a managed host, the control panel, usually under access logs or raw logs, rotated daily. On your own server,
/var/log/nginx/access.logor/var/log/apache2/access.log. Behind a CDN, the origin log shows the CDN's IP addresses, so you need the CDN's own log or an origin header that carries the real client IP.Download a couple of days and work on the copy.
# Who is hitting the site at all
awk '{print $1}' access.log | sort | uniq -c | sort -rn | head -20# How many requests claim to be a crawler
grep -Eic 'googlebot|bingbot' access.log# Which paths the crawler actually fetched, busiest first
grep -Ei 'googlebot' access.log | awk '{print $7}' | sort | uniq -c | sort -rn | head -20# What we served it
grep -Ei 'googlebot' access.log | awk '{print $9}' | sort | uniq -c | sort -rnThe field numbers (
$1,$7,$9) assume the combined log format: client IP, identity, user, timestamp, request, status, bytes, referrer, user agent. Check the first line of the file and the server config before trusting them.A user agent proves nothing. Anyone can send the word Googlebot. Verify the IP by reverse lookup, then forward-resolve the name it returns and confirm it comes back to the same IP:
host 66.249.66.1
# the returned name should sit under googlebot.com or google.com
host <the-name-it-returned>If either lookup fails, or the forward lookup does not return the original IP, that hit was somebody else. Usually a scraper or a monitoring service.
What real crawling looks like: more than one hit, spread over several days; requests for HTML pages rather than only images and CSS; 200 responses; and a spread of URLs that includes internal pages, not just the home page.
What it does not look like: a single hit on the home page, a run of hits on the login path, or hits only on assets. Those are fetchers and scanners, not indexing.
The self-inflicted block. If you switched on a firewall bot rule, a rate limit, or a security feature that blocks suspicious traffic during launch week, check it before concluding anything about the index. The log will show 403s or 429s served to a crawler. That is your own rule, not a search engine decision.
Inquiries: prove the path works end to end
Submit the form yourself on launch day, from a network that is not yours, using a mailbox you control. Confirm four separate things:- the thank-you message appears
- the notification email arrives
- the entry is stored somewhere you can query
- the sender address passes SPF, DKIM and DMARC for your domain
The email is the fragile part. It can fail while the form still looks fine to the visitor. Check the spam folder, then check the host's mail log for the message ID. If the mail path turns out to be unreliable, at least store every submission so nothing is lost.
Server-side proof that a submission reached you, even when the email did not:
grep 'POST ' access.log | awk '{print $7, $9}' | sort | uniq -c | sort -rn | head
A 200 on the form handler means the data arrived somewhere. A 500 means the handler is failing and the visitor saw an error or a blank page. A 429 means your own rate limit ate a real inquiry.
Separating noise from a real inquiry. Noise usually looks like this: the same IP hitting the handler several times in a few minutes, fields that are empty or obviously generated, a message body that is only a link, a referrer from a directory site. A real one usually has a company name you can look up, a reply-to address that matches the domain in the message, and a specific question about a specific thing.
That is a set of heuristics, not a rule. Read the message.
The week-one sheet
WhatWhereNormal in week onePages known / indexedSearch Console pages reporta small number, growing slowlyCrawl requestsaccess log, filtered by verified crawler IPsa handful per day, spread across URLs4xx / 5xx on canonical URLsaccess logclose to zeroForm POSTsaccess logequals the number of inquiries you receivedInquiriesinbox or a shared sheetany number, including zeroTop referrersanalyticsmostly direct and your own links early on
One place, filled in daily. Five minutes a day.
The form POST count and the inquiry count should match. If they do not, you have a delivery problem, not a traffic problem.What not to conclude in week one
- Zero indexed pages on day 3 is not a penalty.
- Zero inquiries from fifteen visitors is not a conversion problem. It is a traffic problem, and it is too early to see either.
- Do not rewrite the site on five days of data.
- Do not resubmit anything twice. Once is the instruction; the second time is noise in your own process.
The whole first week is a verification exercise: is the door open, is anyone walking through it, and does the contact path actually deliver. Everything after that is content, which runs on a much slower clock.#seo #startup #webdev #software #coding #development #engineering #inclusive #community
Launch week: what to submit, what the logs should show, and how to tell a real inquiry from noise -

🏆 New Achievement! A Thousand Lobbies, All Pointing At Your Pocket!
Magnificent, really. Whoever built this infrastructure has a gift. Hundreds of compromised websites — tens of millions of monthly visitors flowing through — repurposed into a gleaming, silent delivery network for iPhone spyware. No ropes, no signs, no warning tiles. Just a perfectly load-bearing trap disguised as the internet's ordinary furniture. (1/3)
-

Daphne and the Pirate
(1916)movie
Gish, Lillian, 1893-1993; Dexter, Elliott, 1870-1941; Motion picture actors and actresses-United States; Silent films-United States; Swashbuckler films - United States; Motion pictures-United States;
Movie Poster CollectionFrom Digital Collections of the Los Angeles Public Library
https://tessa2.lapl.org/digital/collection/movie/i…#LosAngeles #LA #California #CA #US #USA #history #image #historical #photo #photos
-

Admission: in a time when I was interviewing a lot of candidates, I had never heard of systems that keep track of people’s names which use the value `FNU` if a first name is omitted (First Name Unknown. Similarly for last names, `LNU`)
So one day, I get an interview assignment for a candidate Fnu Lâm. (The dumbass system took the FNU magic string and formatted it as a name.) I had no idea how to pronounce it, so I sought out a colleague with Vietnamese background, and asked “How would you pronounce Fnu?”
“Um… just like you?”
“Oh! So the Fn is silent?”
-
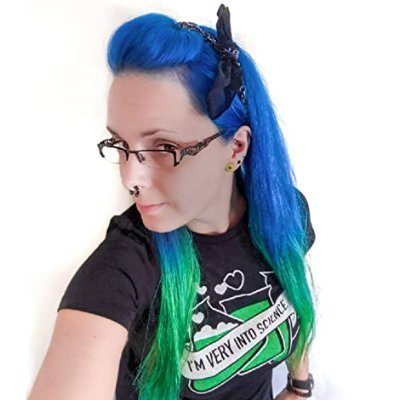
🎃 #Halloween Spooktacular 01 - Creepy Abandoned Hospitals
💉Kill or cure; these decaying medical facilities are long closed. Asylums, their long corridors with peeling paint and smashed windows. Almost pristine hospitals, with the power still on and beds still made. Silent operating theatres and empty wards.
📷 Explore #abandoned hospitals - https://www.obsidianurbexphotography.com/portfolio/abandoned-places/unsanitary-clinical/
#AbandonedPlaces #LostPlace #Portfolio #Macabre #Spooky #Haunted
-
The review usually opens with a demo that looks fine. An agent plans four edits, applies them to a workspace on a remote box, and reports success; the tests are green and everyone relaxes. Two hours later a human's refactor is gone, and nobody can point at the request that removed it. Is that a model problem, a server problem, or a protocol problem?
I think it is a protocol problem almost every time, and I want to make the case with an executable fixture rather than an architecture diagram. Below is the event order I keep reconstructing in reviews, the invariant it violates, and a small simulator that will fail your design for you. Everything here is a model of a system, not a benchmark of a vendor.
1. The event order that silently wins
A planner reads the workspace at revision 0 and emits three steps againstapp.py. Step 1 applies and the workspace moves to revision 1. While step 2 is in flight, either a human edits that file or the session is re-routed to a different model that re-plans the remainder; both are ordinary events, not incidents.Step 2 still carries the content hash it was planned against. If the executor applies patches by path without checking that hash or the revision, the write lands on content the planner never saw, and the old bytes vanish. Nobody gets an error, because a patch is not a request — it is a claim about a state that may already be false.
The failure is invisible precisely when it is most expensive. The agent's summary says "updated handler and tests", the test run passes because the overwritten hunk was unrelated, and the loss only surfaces at the next merge. Who is supposed to notice that?
2. The invariant, stated once
No step may be applied unless the state it was planned against is still the state it is applied to, or the step has been explicitly rebased onto the new state.That is it. Note what the invariant does not say: it does not say a step is correct, and it does not say a retried step is safe. A revision fence prevents stale acceptance; idempotency prevents double application. Teams routinely build one, assume they have the other, and then argue about whose bug it is.
3. Declared assumptions
- One writer per file at a time; concurrent multi-writer edits are out of scope and need a merge protocol, not a fence.
- The workspace has a monotonic revision counter and a per-file content hash that are both persisted with the workspace itself.
- A step is planned from a readable snapshot and carries
(step_id, base_rev, path, pre_hash, patch). - Execution may be preempted at any point between "patch written" and "client received the result".
- Model identity may change inside a session, because routing, fallback, or a free-tier allowance running out can move you to another model without warning.
4. Data flow and failure domains
There are three state holders and they fail independently: the planner's context (lossy, model-dependent), the executor's workspace (authoritative, preemptible), and the client's view of progress (optimistic, retried). The only durable truth is the workspace plus whatever journal you persist alongside it.Failure domains worth separating in review: stale plan (planner state diverged), lost ack (executor applied, client did not learn), duplicate delivery (client retried an applied step), and re-plan drift (a new model emits steps against an old base). They need different mechanisms, and a single retry counter hides all four.
5. The fixture
This is deterministic Python with no model calls, so the verdicts below are properties of the protocol, not of any provider.# fence_sim.py - deterministic, no LLM involved
from dataclasses import dataclass@dataclass(frozen=True)
class Step:
step_id: str
base_rev: int
path: str
pre_hash: str
patch: strclass Workspace:
def __init__(self):
self.rev = 0
self.files = {"app.py": "v0"}
self.journal = set() # persisted with the workspace
def hash(self, path):
return self.files
[path] def write(self, path, content):
self.files[path] = content
self.rev += 1class Executor:
"""fence: 'none' | 'plan' | 'step'; dedupe: journal-backed idempotency"""
def __init__(self, ws, fence="step", dedupe=True):
self.ws, self.fence, self.dedupe = ws, fence, dedupe
self.plan_rev = None
def plan(self, rev):
self.plan_rev = rev
def stamp(self, s):
if self.fence == "step":
return Step(s.step_id, self.ws.rev, s.path, self.ws.hash(s.path), s.patch)
if self.fence == "plan":
return Step(s.step_id, self.plan_rev, s.path, s.pre_hash, s.patch)
return s
def exec(self, s):
s = self.stamp(s)
key = (s.step_id, s.base_rev)
if self.dedupe and key in self.ws.journal:
return "deduped"
if self.fence != "none":
if s.base_rev != self.ws.rev:
return "rejected:stale_rev"
if self.ws.hash(s.path) != s.pre_hash:
return "rejected:pre_hash"
self.ws.write(s.path, s.patch)
if self.dedupe:
self.ws.journal.add(key)
return "applied"Two lines deserve attention. The journal lives in
Workspace, not in the executor, because an in-process dedupe set dies with the server that was preempted — which is exactly the trap. Andstampis where fence granularity is decided, so you can argue about it in one place.6. Injecting the three failures
Run the same three scenarios across fence modes and record the verdicts. The interference classes are injected explicitly, so the denominator is the number of injections, not the number of suspicious log lines.def scenario_concurrent_edit(fence):
ws = Workspace(); ex = Executor(ws, fence=fence); ex.plan(ws.rev)
s1 = Step("s1", 0, "app.py", "v0", "v1")
s2 = Step("s2", 1, "app.py", "v1", "v2")
assert ex.exec(s1) == "applied"
ws.write("app.py", "human-refactor") # interference: rev 2
return ex.exec(s2)def scenario_preemption_retry(fence):
ws = Workspace(); ex = Executor(ws, fence=fence)
s1 = Step("s1", 0, "app.py", "v0", "v1")
ex.exec(s1)
# ack lost; client replays s1 against a fresh executor, same persisted workspace
return Executor(ws, fence=fence).exec(s1)def scenario_replan_drift(fence):
ws = Workspace(); ex = Executor(ws, fence=fence); ex.plan(ws.rev)
ex.exec(Step("s1", 0, "app.py", "v0", "v1"))
ex.plan(ws.rev) # new model re-plans from rev 1
return ex.exec(Step("s2", 0, "app.py", "v0", "v1-tail"))Expected output, because the simulation is deterministic and calls no model:
fence=none concurrent_edit -> applied preemption_retry -> applied twice replan_drift -> applied
fence=plan concurrent_edit -> rejected:stale_rev preemption_retry -> rejected:stale_rev replan_drift -> rejected:stale_rev
fence=step concurrent_edit -> rejected:stale_rev preemption_retry -> rejected:stale_rev replan_drift -> applied
dedupe on concurrent_edit -> rejected:stale_rev preemption_retry -> deduped replan_drift -> appliedRead the second and third rows together, because that is the argument. A plan-level fence turns every retry into a spurious rejection and every legitimate re-plan into a dead end; it is loud, but it is loud in the wrong places. A step-level fence plus a persisted journal gets you the two properties you actually want, and it costs you a durable set of
(step_id, base_rev)keys.7. Making it a property, not a demo
Three scenarios are an anecdote. Turn them into invariants and let a random interleaving search hunt for violations — this is the part I would block a design review on.def invariants_hold(ws, results):
# P1: every applied step saw base_rev == rev at apply time
assert all(r.rev_at_apply == r.base_rev for r in results if r.status == "applied")
# P2: journal is append-only per (step_id, base_rev)
assert ws.journal == set(ws.journal)
# P3: no path content was replaced by a step older than the current rev
assert all(r.base_rev <= r.rev_at_apply for r in results)Then fuzz: shuffle
{human_edit, preempt, retry, replan, duplicate_delivery}over a fixed step list, run 5,000 seeds, and assert P1 and P2 for every seed with fences on. Run the same search withfence="none"to extract a minimal counterexample, and put that event order in the PR description as the regression case. A protocol claim without a counterexample search is a preference.8. Where the free tier changes the arithmetic
If your executor is a shared, preemptible environment and your planner can move between models at any time, then re-plan drift and lost acks are not edge cases — they are the steady state. That is the actual architectural consequence of running agents on free resources, and it argues for cheap, persisted fences rather than expensive coordination.I use MonkeyCode as the concrete instance of that environment in this review: it is an open-source coding agent whose operator supplies free model access (currently advertised as a 10M-token allowance) and a free server option. Treat those numbers as operator-supplied and re-verify them on the project page before you design around them, because allowances and routing change faster than any architecture does. My interest here is narrow: a free server makes preemption ordinary, and free model access makes mid-session re-routing ordinary, so both of my injected interferences become Tuesday.
Disclosure: This article was prepared as part of MonkeyCode's product outreach.
9. Tradeoffs I would write down
MechanismBuys youCosts youFails whenNo fenceThroughput, simplicitySilent lost updatesAny concurrent editPlan-level fenceLoud, cheap rejectionRe-planning whole plans, spurious retriesModel swap or long plansStep-level fencePrecise staleness detectionA re-stamp on every dispatchSemantic overlap between stepsPersisted journalIdempotent retry across preemptionDurable key storage, growth controlJournal not persisted atomically with the writeCheckpoint per stepFast compensationStorage, restore latencyLarge binaries, long test suites10. Verdicts: reject, replay, or compensate
Event orderCorrect verdictWhyStep arrives,base_rev< current rev, no overlapReject, re-plan from current revThe plan is stale; the patch is not recoverableStep arrives, journal contains(step_id, base_rev)Replay the stored resultThe work is done; the ack is what was lostStep applied, tests for touched files failCompensate to the checkpointFence passed, semantics did notNew model re-plans mid-session from current revAccept if re-stamped and preconditions holdDrift is expected, staleness is notTwo steps with overlapping hunks in one planReject the plan at admissionA fence cannot order siblings11. What I would change next
- Persist the revision counter, file hashes, and journal in one atomic write, so a crash cannot leave a patch without its key.
- Stamp
base_revat dispatch, never at plan time, and log both values — the delta is your drift signal. - Bound the journal by session and drop it only after a checkpoint the workspace itself can prove.
- Run the fuzz job in CI with fences on, and store the minimal counterexample from
fence="none"as a named regression seed. - Add a sibling-overlap check at plan admission, because per-step fences order nothing within a plan.
12. Limits, and who should skip this
The fixture models file-level hashing and a single writer; it says nothing about merge semantics, and it does not evaluate whether a patch was any good. If your model swap also changes plan quality, this protocol will happily accept a worse plan that happens to be revision-correct. That is a separate evaluation problem, and no fence will solve it for you.Skip this if your agent is single-turn and single-file with a human watching every apply, if your platform already gives each step an atomic worktree or VM snapshot, or if you cannot persist a journal durably — half of this mechanism without the journal is worse than none, because it rejects retries without making them safe.
So here is the question I would leave in the review thread: which event order in your system breaks the invariant — a human edit racing step two, an ack lost after the write, or a re-plan against a stale base — and for that specific order, should the executor reject, replay, or compensate?#ai #architecture #distributed #testing #software #coding #development #engineering #inclusive #community
Treat a Coding-Agent Step as a Revision-Fenced Command, Not a Prompt -
Quick Answer
A fleet tracking backend should treat every GPS ping as untrusted input. Sort pings by device time, drop duplicates and impossible values, reject poor fixes and teleport jumps, hold position while a vehicle is parked, and add hysteresis to geofences. Keep the raw stream, store the cleaned stream beside it, and snap to roads only after cleaning. The Python below was tested on synthetic data only, not on live device feeds.Why does a fleet app receive bad GPS data?
Some of the reasons are written down in vendor documentation. Samsara's vehicle locations documentation says a device reports about every 5 seconds while the vehicle is on and about once an hour while it is off. It also says identical consecutive records can occur, and that GPS interference in a garage can suppress updates even when the vehicle shows as on. The same page says the device keeps a rolling 30 days of location data, so after a connection is restored the buffered points become available through the API.Read together, those statements describe four problems a backend must expect: duplicate rows, silent gaps, a misleading "on" status, and late data that arrives out of order. This is one vendor's documentation. Other vendors will behave differently, so read the equivalent page for the device you actually use.
What should the ingest layer check before it stores a ping?
My suggestion (author judgement, not a standard) is six cheap checks, run in this order:- Sort by device timestamp, so late arrivals land in the right place.
- Drop exact duplicates (same time and position).
- Reject impossible values, including out-of-range coordinates and the 0,0 position that some receivers report before they have a fix.
- Reject poor fixes, where the reported accuracy is worse than a threshold.
- Reject teleport jumps, where the implied speed between two kept points is not plausible for a vehicle.
- Hold position while parked, so receiver jitter does not draw a wandering trail.
The thresholds in the code (50 m accuracy, 45 m/s, 10 m jitter) are starting values I chose for the example. Tune them against your own vehicles and devices.
from dataclasses import dataclass
from math import radians, sin, cos, asin, sqrt@dataclass(frozen=True)
class Ping:
device: str
ts: int # epoch seconds, device clock
lat: float
lon: float
acc_m: float = 10 # reported horizontal accuracy in metresdef haversine_m(a, b):
r = 6371000.0
p1, p2 = radians(a.lat), radians(b.lat)
dp, dl = p2 - p1, radians(b.lon - a.lon)
h = sin(dp / 2) ** 2 + cos(p1) * cos(p2) * sin(dl / 2) ** 2
return 2 * r * asin(sqrt(h))def clean(pings, max_acc_m=50, max_speed_ms=45, jitter_m=10):
"""Return a cleaned, time-ordered list for ONE device."""
seen, ordered = set(),
[] for p in sorted(pings, key=lambda p: p.ts): # 1. fix ordering
key = (p.ts, round(p.lat, 6), round(p.lon, 6))
if key in seen: # 2. drop duplicates
continue
seen.add(key)
if not (-90 <= p.lat <= 90 and -180 <= p.lon <= 180): # 3. impossible values
continue
if p.lat == 0 and p.lon == 0: # "null island" fix
continue
if p.acc_m > max_acc_m: # 4. poor fix
continue
ordered.append(p)out =
[] for p in ordered:
if out:
prev, dt = out[-1], p.ts - out[-1].ts
if dt <= 0:
continue
d = haversine_m(prev, p)
if d / dt > max_speed_ms: # 5. teleport jump
continue
if d < max(jitter_m, p.acc_m): # 6. parked jitter
p = Ping(p.device, p.ts, prev.lat, prev.lon, p.acc_m)
out.append(p)
return outTesting status: I ran six unit tests with Python 3.13 on synthetic points: out-of-order input, duplicates, 0,0 and poor-accuracy points, a teleport jump, parked jitter, and geofence flapping. All six passed. I have not run this against real device feeds, so treat it as a teaching sample and not production code.
How do you stop geofence alerts from flapping?
A vehicle parked near the edge of a depot boundary can cross it back and forth because of receiver noise, and each crossing can fire an alert. Two techniques help. Use hysteresis, which means the vehicle enters a zone inside radius r but only exits beyond r plus a buffer. Then require several consecutive pings before the state changes.class Geofence:
"""Circle fence with hysteresis: enter inside r, exit only outside r + buffer."""
def __init__(self, lat, lon, r_m, buffer_m=30, confirm=2):
self.c = Ping("fence", 0, lat, lon)
self.r, self.buf, self.confirm = r_m, buffer_m, confirm
self.inside, self._streak = False, 0def update(self, p):
d = haversine_m(self.c, p)
want_inside = d <= self.r if not self.inside else d <= self.r + self.buf
if want_inside == self.inside:
self._streak = 0
return None
self._streak += 1
if self._streak >= self.confirm:
self.inside, self._streak = want_inside, 0
return "enter" if self.inside else "exit"
return NoneIn the test, a sequence of distances of 150, 90, 95, 110, 98, 105, 160 and 170 metres from a 100 m fence produced exactly one enter event and one exit event. Two of those readings (110 m and 105 m) were outside the 100 m radius while the vehicle was still inside the zone, and the buffer absorbed both.
Should you snap points to roads?
Map matching can clean what the filters above leave behind, but it has its own rules. Google's Roads API documentation says one snap-to-roads request accepts up to 100 GPS points and returns points snapped to the most likely road. It recommends keeping consecutive points at or below about 300 metres apart, and offers an optional interpolate setting that adds points following the road shape. Interpolated points have no original index, so the response can contain more points than the request.OSRM's Match service takes optional timestamps, which must increase, and optional per-point radiuses that default to 5 metres. The documentation suggests using the device's reported accuracy. It returns null for points dropped as outliers and a confidence score from 0 to 1 for each matching. The OSRM page I read was for version 5.5.1, so check the documentation for the version you run.
My judgement: snap after cleaning, keep the raw point and the snapped point side by side, and treat a low confidence score as a flag for review rather than an error.
How do you find vehicles near a depot quickly?
PostGIS documents ST_DWithin as a cheap filter that can use a spatial index, while ST_Distance computes exact distances and cannot use indexes. For geography values the distance is in metres. The common pattern is to filter with ST_DWithin first and sort with ST_Distance on what remains.SELECT v.id, ST_Distance(v.last_position, d.location) AS metres
FROM vehicles v
JOIN depots d ON d.id = 7
WHERE ST_DWithin(v.last_position, d.location, 2000)
ORDER BY metres;This query is untested. It assumes both columns are
geographywith a spatial index onlast_position, so check the types and the index in your own schema.What should the fleet database store?
In my view three tables cover most needs: an append-only table of raw pings, a table of cleaned pings that maps and reports read, and a small table holding the last known position per vehicle for proximity queries. Keeping the raw data lets you re-run a better filter later and settle disputes about a route.Which are the top five fleet management app development companies?
Teams that prefer to buy this work instead of building it can compare the five partners below. The list is not a ranking of quality.Figures below come from each company's own website and are self-reported, so confirm them directly before signing anything.
1. Dev Technosys
Dev Technosys is a fleet management app development company with 250+ professionals that does business globally. Its fleet page describes connecting GPS tracking, fuel monitoring and dispatching systems, then automating assignments, maintenance alerts and journey updates. The company builds its own platforms and connects them to existing business systems through APIs instead of configuring third-party ERP products. It states an 89% project success rate and says most new business comes through client referrals; both claims are self-reported. That scope fits teams that already own tracking hardware and need workflow software around it.2. N-iX
N-iX lists fleet management software development as a dedicated service. Its page covers telematics and predictive-maintenance integration, ELD and IoT sensor integration, hours-of-service compliance modules, route-planning and dispatch engines, and mobile fleet apps. A case study describes a GPS-tracked in-vehicle Linux gateway, a Google Cloud IoT platform and an Android driver app for a telematics client, in a partnership that began in February 2021. The site states over 2,400 software engineers, and the case study gives no fleet outcome figures. N-iX suits teams that need hardware-to-cloud telematics work from one vendor.3. Intellias
Two fleet case studies sit on the Intellias site. In the first, a Florida telematics client has worked with the company since 2018 on a platform with real-time GPS mapping, idle-time tracking and diagnostic trouble code reporting, and the page says it handles 100,000+ vehicles with data points every 30 seconds. The second is a native iOS, Android and Angular truck-tracking front end for a large car maker, tested on 1,000 vehicles and offered in more than 20 countries. Intellias suits teams that expect high vehicle counts and need a backend built for that volume.4. Altoros
Altoros says it was founded in 2001 and lists GPS tracking software for car rental, trucking and delivery, fleet management with vehicle tracking and dispatch, and IoT platforms for fleets. Its logistics page cites a transport management case serving 100+ companies and processing 10,000+ automated orders a day, with operator workload cut by up to 70%, plus a truck-parking app prototype covering 10,000+ locations. All of these figures are self-reported, and the page names no ISO certification, so ask for evidence. Altoros suits teams that want an IoT-heavy build from a long-established vendor.5. STX Next
Describing itself as a Python-native team with more than 20 years of experience, STX Next lists fleet management systems, route optimization, electronic proof of delivery, predictive maintenance and IoT integration on its transport and logistics page. Named case studies include Sendcloud (a carrier integration proof of concept), GS1 Polska (a location-data app for drivers) and T Dispatch (dispatch software). The page mentions Python, IoT, RFID, AWS, Azure and Snowflake and lists delivery centers in Poznan and Merida, but it states no headcount. STX Next suits teams that prefer a Python backend.FAQ
How often should a fleet device send a position?Samsara's documentation describes about every 5 seconds while a vehicle is on and about hourly while it is off. Your hardware and data plan set the real figure.
Should raw pings be deleted after cleaning?
In my view, no. Keep them for a retention period your own policy allows, so you can re-run improved filters later.
Do I need map matching in every fleet app?
No. Many dashboards work with cleaned points. Matching helps most when you report distance driven on roads.
What accuracy threshold should I use?
The example uses 50 m as a starting value. Tune it per vehicle type and device.
Can I use this code in production?
It is a teaching sample tested on synthetic data. Add tests built from real device samples first.#python #backend #iot #architecture #software #coding #development #engineering #inclusive #community
Designing a Fleet Tracking Backend That Handles Bad GPS Data -
AI can generate a financial model that looks coherent, contains valid formulas, and produces a plausible result while still being wrong in ways that matter.
A formula can reference the wrong cell. A cost assumption can be expressed in the wrong unit. A revenue schedule can omit a phase. A model can calculate correctly from an unsupported market assumption.
These are different failure modes, and they need different controls. For real estate feasibility models, the objective should not be to ask whether an AI-generated workbook looks correct. It should be to establish which properties can be tested automatically, which assumptions require evidence, and which decisions must remain with a qualified human reviewer.
A useful validation architecture has five layers:
- Structural validation
- Deterministic calculation checks
- Domain and consistency checks
- Evidence and provenance checks
- Human review and approval
No single layer is sufficient.
1. Separate the output from the evidence
Consider a hypothetical development model with the following inputs:- Site area and developable area
- Permitted gross floor area
- Unit mix or lettable area
- Revenue assumptions
- Construction and other development costs
- Financing assumptions
- Development programme
- Exit assumptions
The model calculates development costs, revenue, cash flows, residual land value (RLV), and potentially internal rate of return (IRR).
For example, a model might calculate an RLV of £4 million. That output can be mathematically consistent with the workbook and still be commercially misleading if the revenue assumptions are unsupported or the construction cost basis is outdated. Validation therefore needs to test both the calculation and the justification for its inputs.
2. Layer one: validate the structure before the numbers
Before reviewing financial logic, validate the shape of the generated output. If an AI system is expected to return structured data before creating a workbook, define an explicit contract. JSON Schema is one established option for specifying required fields, data types, and constraints.See the JSON Schema getting-started guide.
A simplified model input contract might look like this:
{
"project_id": "DEMO-001",
"currency": "GBP",
"site_area_sqm": 5000,
"gross_floor_area_sqm": 12000,
"construction_cost_per_sqm": 1800
}
This is illustrative data, not a market benchmark or a recommendation for a production schema.A structural validator could check that:
- Required fields are present.
- Numeric values are actually numeric.
- Areas and costs use declared units.
- Currency is explicitly identified.
- Values fall within defined technical bounds.
- Unexpected fields are rejected or handled deliberately.
- Missing values are not silently replaced with zero.
The last point is important. Zero and unknown are not equivalent. If a finance rate is missing, substituting zero can make a model appear more profitable. A missing value should normally trigger a validation error or an explicit unresolved status.
Structural validation establishes that the model can be interpreted. It does not establish that the model is economically sensible.
3. Layer two: use deterministic checks for deterministic rules
Rules that can be expressed precisely should not depend on an LLM's judgment. For example, if a model defines construction cost as gross floor area multiplied by construction cost per square metre, the expected calculation is:\text{GFA}
\times
\text{Cost per sqm}
]
For the hypothetical inputs above:
[
12{,}000 \times £1{,}800 = £21{,}600{,}000
]
A deterministic test can independently calculate the expected result and compare it with the workbook output.
from decimal import Decimalgfa_sqm = Decimal("12000")
cost_per_sqm = Decimal("1800")
reported_cost = Decimal("21600000")expected_cost = gfa_sqm * cost_per_sqm
assert expected_cost == reported_cost
This test checks arithmetic for the stated formula. It does not establish that the GFA is permitted, that the cost rate is appropriate, or that the formula captures every relevant cost.
A production implementation should also define tolerances where appropriate, particularly when comparing rounded spreadsheet values or calculations involving floating-point numbers.
Other deterministic checks might include:
Revenue equals the sum of its components.- Total costs reconcile to their component schedules.
- Cash flow totals reconcile across periods.
- Unit counts and areas reconcile between schedules.
- The reported output matches an independently calculated result.
- A sensitivity case actually changes the intended input.
- Required formula cells are not unexpectedly blank or replaced by constants.
Where possible, use independent calculations rather than simply checking that a formula cell contains a formula. A formula can exist and still be wrong.
4. Layer three: validate model relationships
Many serious errors are not syntax errors or arithmetic errors. They are inconsistencies between parts of the model.Suppose a development model contains:
- 120 residential units in the unit schedule
- 116 units in the sales schedule
- Revenue calculated using the sales schedule
- Construction costs calculated using the unit schedule
Every formula may evaluate successfully, but the workbook contains a discrepancy that needs resolution.
Domain-level checks can flag conditions such as:
- Unit counts that differ across schedules.
- Areas that exceed a declared model constraint.
- Revenue periods that do not align with the programme.
- Cost totals that exclude a populated cost category.
- An exit value that uses an inconsistent timing assumption.
- A sensitivity scenario that changes revenue but leaves dependent calculations unchanged.
- An IRR calculation using a cash-flow range that omits a period.
These checks should be encoded as explicit rules wherever the intended relationship is known.
Some rules require context. For example, whether a particular cost should be included in a development budget depends on the model's scope and conventions. A validator should not impose a universal rule where none exists.
Instead, it should identify the relevant condition, record the rule being applied, and send ambiguous cases for review.
5. Layer four: validate the provenance of assumptions
A financial model can pass every arithmetic test and still fail as an analytical tool.The reason is straightforward: calculations cannot establish the truth of their inputs.
For every material assumption, a validation system should try to preserve:
- The value and unit.
- The source or origin of the value.
- The source's date and relevant data period.
- The geography and asset type, where applicable.
- The transformation from source evidence to model assumption.
- Any manual adjustment made by the analyst.
- The model locations that depend on the assumption.
Consider a construction cost assumption of £1,800 per square metre. A validator might confirm that the figure is numeric, the unit is recorded, and the workbook uses it consistently. Those checks do not establish whether the figure is suitable for the location, asset type, specification, and cost period. That question requires appropriate evidence and professional interpretation.
An LLM may help extract candidate assumptions from documents or explain how a value is used in a workbook. The extracted result should still be checked against its source, and the resulting assumption should remain distinguishable from the underlying evidence.
A useful principle is:
Traceability makes an assumption inspectable. It does not make the assumption correct.6. Layer five: make human review a defined state transition
Human review should not be an informal final glance after an automated process has already treated the model as complete.A practical workflow can represent validation explicitly:
GENERATED
|
v
STRUCTURE_CHECKED
|
v
CALCULATIONS_CHECKED
|
v
DOMAIN_CHECKED
|
v
EVIDENCE_REVIEWED
|
v
HUMAN_APPROVAL_REQUIRED
|
+----> APPROVED FOR THE DEFINED PURPOSE
|
+----> RETURNED FOR CORRECTION
|
+----> BLOCKED: UNRESOLVED ISSUEThe states are illustrative, but the distinction matters. A successful automated test should not automatically mean that a model is approved. Approval should be scoped to a defined version of the workbook, its assumptions, its evidence, and its intended use.
A reviewer should be able to see:- What was generated.
- Which automated checks passed.
- Which checks failed or were skipped.
- Which assumptions lack adequate evidence.
- What changed after a correction.
- Who approved the model and for what purpose.
If a material input or formula changes after approval, the system should identify which checks need to run again and whether the earlier approval remains valid. This is where versioning and change tracking become part of model governance rather than administrative overhead.
7. Design the exception path before the success path
Validation is often designed around a clean example: the model is generated, every check passes, and the user receives the output. Production systems need to handle less convenient outcomes.A failed check should produce actionable information. “Validation failed” is less useful than “The unit count in the sales schedule differs from the unit schedule; review the linked inputs before approving revenue.”
Similarly, a warning should not disappear simply because a later stage of the workflow succeeds. For auditability, preserve the check identifier, the model version, the result, the relevant evidence, and the resolution.
8. Measure validation quality without inventing an accuracy score
A single “model accuracy” percentage can hide important distinctions. A workbook might pass every arithmetic test while containing several unsupported assumptions. Another may contain a harmless formatting issue but have fully reconciled calculations and well-documented inputs.A more useful validation report separates categories:
- Structural checks passed or failed.
- Deterministic calculation checks passed or failed.
- Domain checks passed, failed, or were not applicable.
- Assumptions with verified, missing, or conflicting evidence.
- Open exceptions and their severity.
- Human review status.
- The scope and version of the approved output.
If the system is evaluated over time, track false negatives and false positives for individual validation rules against a reviewed test set. Record the test cases, expected outcomes, rule versions, and known limitations.
Do not interpret a high pass rate as proof that the model is correct. It may simply mean that the checks cover only a narrow set of failure modes.
The purpose of validation is to make known risks visible and testable, not to manufacture certainty.
9. A practical implementation sequence
A team introducing validation around AI-generated financial models does not need to automate every review step at once.A sensible sequence is:
- Define the contract. Specify the required inputs, output fields, units, and missing-value behaviour.
- Write deterministic tests. Start with totals, reconciliations, formula ranges, and independent calculations.
- Add domain checks. Encode known cross-schedule relationships and clearly defined constraints.
- Track provenance. Associate material assumptions with sources, dates, units, and transformations.
- Introduce exception handling. Make failures explicit and prevent unresolved material issues from being silently treated as passed.
- Define human approval. Record the reviewer, workbook version, purpose, and outstanding qualifications.
- Build a regression suite. Retain representative valid and invalid examples and rerun the checks when the generation logic or validation rules change.
The test suite should include deliberate failures, not only successful examples. Examples might include missing finance assumptions, inconsistent unit counts, a formula referencing the wrong period, and a source whose geography does not match the project.
This helps test whether the validation process detects the intended problem rather than merely accepting a plausible-looking output.
Conclusion
Human-in-the-loop validation is not a person checking an AI result after the important work is finished. It is a system design in which deterministic rules handle deterministic questions, domain checks expose inconsistencies, evidence is kept separate from assumptions, and a human reviewer remains accountable for unresolved judgments.For financial modelling, that distinction is material. A workbook can be well-formed without being economically sound, mathematically consistent without being supported by market evidence, and ready for review without being ready for a decision.
The objective is not to make every AI-generated model look trustworthy. It is to make the model's logic, assumptions, limitations, and unresolved issues sufficiently visible that a professional can challenge it before relying on the result.#feasibility #realestate #ai #financial #software #coding #development #engineering #inclusive #community
Human-in-the-Loop Validation for AI-Generated Financial Models -

The scenario below is fictional (all IPs are RFC 5737 documentation ranges).
The worst moment in an investigation is realizing the logs are gone. It's tempting to conclude the attacker was better than you. That's only half true: the act of erasing evidence leaves new evidence.This is part 2 of a series. Part 1 showed one micro-technique (recovering a deleted binary from
/proc). Here is the map: seven principles every later part fits into.What you'll learn
- Which traces attackers can erase, and which they can't
- Seven principles for reading traces without getting lost
- A 3-question audit you can run on your own servers
Four kinds of traces
KindExamplesCan the attacker erase it?Self-reported.bash_history, app logsEasilyRuntime state/proc/<PID>/, live connectionsNot without stopping the processKernel/OS recordsauditd, Windows event logs, file ctimeNeeds privilege, and erasing leaves a recordOff-host recordscentral logs, firewall/flow logs, cloud logsOut of reachThe seven principles
- Read traces from the attacker's point of view. Foothold, persistence, lateral movement, cleanup: each step has predictable places to leave marks.
- Know normal, then diff. Detection is mostly "difference from baseline", not "spot the weird".
- Traces are redundant. One action shadows several places. If one is wiped, another corroborates.
- Deleted and silent are evidence. A log that stops is itself data. Report "no logs" as unverified, never as safe.
- Normalize to UTC, build one timeline.
- Separate fact from inference. "ctime is 02:23" is a fact. "They got in at 02:23" is a hypothesis.
- Don't stop at detection. Feed findings back into design: central logging, immutability, least privilege.
Three questions for tomorrow
- Are execution records sent somewhere the server itself can't erase?
- Can you describe your "normal admin path" (bastion, accounts, maintenance window) in writing?
- If a log stops, will anyone notice?
Takeaways
Attackers can erase their own diary, but not the OS's and the network's records. Next: a file backdated to 2018 withtouch, caught with one line.Adapted from chapter 1 of my Japanese book on server defense (40 chapters, Windows and Linux, MITRE ATT&CK-mapped, with a laptop-sized lab).#security #forensics #incidentresponse #linux #software #coding #development #engineering #inclusive #community
Deleted is evidence: what attackers cannot erase, in 7 principles -

HOA Antenna Rules: Why Hams Want a Change
Ham radio groups want more room for home antennas. An HOA group wants boards to keep more control. Here’s what the debate means for your shack.
You have the rig. You have your license. Now you need a place to put the antenna.
For hams who live in a homeowners association, or HOA, that last step can be tough. HOA antenna restrictions can limit what you put up, where it goes, or whether you can have an outdoor antenna at all.
A proposed law called the Amateur Radio Emergency Preparedness Act aims to help. Its two bills are H.R. 1094 in the House and S. 459 in the Senate. ARRL backs the effort. The Community Associations Institute, or CAI, opposes it.
Why is this back in the news?
Amateur Radio Daily covered the issue on October 21. It pointed to a September 21 statement from CAI about its plans for meetings with Congress.
CAI wants lawmakers to oppose both bills. It says the plan would limit an HOA’s power to require approval before a ham puts up an antenna. That is CAI’s view. It does not mean every HOA board agrees.
This news is about groups trying to shape a law. It does not report a new vote or give hams new antenna rights.
Doesn’t an FCC license protect my antenna?
This is where many hams get stuck. Town rules and private property rules are two different things.
As ARRL explains in its PRB-1 guide, the FCC’s PRB-1 policy requires local governments to make reasonable room for ham radio. Towns may still have rules about height, safety, and how an antenna looks.
But PRB-1 does not cover private deed limits, often called covenants or CC&Rs. An HOA rule can be a separate hurdle, even when the town allows your antenna. That gap helps explain why hams are asking Congress for a change.
What would the bills do?
The House bill’s proposed text would limit private rules that block or hinder ham antennas on property under the ham’s control.
It would also change the approval process. Here are a few parts of the House proposal:
- Some antennas would not need prior approval. These include thin, low-profile wire antennas and certain flagpole and vertical antennas up to 43 feet tall.
- When an application is needed, no answer within 45 days would count as approval.
- Rules for safe structures and building codes would still apply.
The text would also limit how much detail an HOA could demand in an antenna application. After approval, it would generally bar another approval demand unless the antenna’s size or structural strength changed in a major way.
These are parts of a proposed law. They are not a go-ahead to put up an antenna today.
Why is the approval issue such a big deal?
CAI’s stated concern is the loss of control over prior approval. Hams seeking relief want a clear path to an antenna they can use. The bill would set limits on how private rules could stand in that path.
For example, picture a ham who wants a thin wire in the back yard. An approval process can answer questions about its location and supports. But if that process has no clear end, the ham may be left waiting with a silent station. The proposed 45-day rule is meant to put a clock on that wait.
That example shows the practical tension. A board wants a say before work starts. The operator wants that review to lead to a fair, timely answer.
Why do hams care?
A good rig still needs an antenna that can get a signal out. Strict rules can leave a ham with few choices, even for a small or hidden antenna.
In its call for support, ARRL says these rules hurt both everyday ham radio and emergency work. A home station needs a useful antenna before trouble starts.
For many of us, the goal is simple: work a few stations, check into a net, and keep the station ready to help.
Could a stealth antenna help?
A stealth antenna blends in with your home or yard. It may be worth a look if your HOA allows a low-profile setup.
A flagpole can do double duty as an antenna. A thin wire along the roofline may be hard to spot. A small inverted-L goes up, then across, to use the space you have.
My guide, How to Plan a Stealth HF Antenna for a Small Yard, explains all three options. It covers how to measure your space, plan the wire and coax runs, and test the setup. Start with a design that fits the bands you want to work.
Stealth does not mean rule-free. Check your HOA rules and get any needed approval before you buy parts or hang wire. The aim is to keep the antenna less visible while following the rules.
Give your antenna plan a fair chance
If your HOA has an approval path, make your plan easy to understand. A clear sketch can do more than a page full of radio terms. Show where the antenna will go, how tall it will be, and where the coax will run.
- Start with one goal. A wire for a favorite HF band may be easier to plan than a setup meant to cover every band.
- Show the whole job. Include supports, mounting points, and any ground wires the design needs.
- Explain the view. Photos or a simple drawing can show what neighbors would see.
- Keep a paper trail. Save the rules, your application, and written replies. Ask which rule applies if the board says no.
These steps cannot promise approval. They can help both sides discuss the same plan and avoid confusion.
What can you do now?
Read your HOA’s rules before you change your station. If you have a dispute, get help from someone who knows the rules that apply to your home.
To follow the bills, check the official pages for H.R. 1094 and S. 459. To learn how to support the effort, visit ARRL’s HOA action page.
Hams want a fair chance to get on the air from home. This debate is about how much say an HOA should have over the antenna that makes that possible.
Follow Me on Mastodon
#amateurRadio #AmateurRadioEmergencyPreparednessAct #antennaRights #arrl #HR1094 #HamRadio #HOAAntennaRestrictions #PRB1 #S459 #stealthAntennas -

Triangle Event Guide Free Events and Halloween Fun for Monday, October 26, 2026
Monday brings plenty of ways to explore Raleigh, Durham, Cary and the surrounding Triangle. The Triangle event guide for October 26, 2026, features free Halloween activities, a Diwali celebration, comedy, open mic nights and family outings.
Whether the plan is morning storytime with the kids or an evening of games and entertainment, here’s what’s happening around the Triangle.
Family Activities and Halloween EventsTotal Tot Time in Durham
Time: 10 a.m.–noon
Location: W.D. Hill Recreation Center, Durham
Admission: FreeStart the week with Total Tot Time, a free play program for children ages 5 and younger.
Halloween Storytime on the Roof
Time: 10:30 a.m.
Location: The Durham Hotel, Durham
Admission: FreeEnjoy a seasonal morning outing with Halloween Storytime on the Roof at The Durham Hotel.
Trunk or Treat at Gladwell Orthodontics
Time: 5:30–7:30 p.m.
Location: Gladwell Orthodontics North Raleigh
Admission: FreeGet into the Halloween spirit at Gladwell Orthodontics’ North Raleigh trunk-or-treat event.
Fall Carnival at Carolina Pines
Time: 6:30–8 p.m.
Location: Carolina Pines Community Park, Raleigh
Admission: FreeCelebrate the season with a free fall carnival at Carolina Pines Community Park. This evening event offers another option for families looking for Halloween-week activities in Raleigh.
Diwali Celebration in Downtown Cary ParkTime: 6:30–8 p.m.
Location: Downtown Cary Park, Cary
Admission: FreeCelebrate the Festival of Lights at Downtown Cary Park. The free Diwali celebration is a highlight of Monday’s community events in Cary.
Creative Activities, Reading and Community Events
Coloring Vinyl Night
Time: 2–9 p.m.
Location: KōMANA Brewing Company, Cary
Admission: FreeAdd a creative stop to the afternoon or evening with Coloring Vinyl Night at KōMANA Brewing Company.
Silent Reading Club
Time: 6–8 p.m.
Location: The Glass Jug Downtown Durham Taproom
Admission: FreeBring a book and settle in for a relaxed evening at Silent Reading Club in downtown Durham.
Democracy Unfiltered: A Voter Education Series
Time: 6–8 p.m.
Location: Raleigh Brewing, Raleigh
Admission: FreeMake time for civic learning at Democracy Unfiltered, a voter education series hosted at Raleigh Brewing.
Board Game Night
Time: 6–9 p.m.
Location: Bottle Theory, Apex
Admission: FreeSpend Monday evening playing board games at Bottle Theory in Apex.
Comedy, Karaoke and Movie NightEarly Karaoke
Time: Starts at 6 p.m.
Location: The Northside District
Admission: FreeStart the evening with a song at Early Karaoke at The Northside District.
Monday Movie Night
Time: 6:30–9 p.m.
Location: Compass Rose Brewery, Raleigh
Admission: FreeEnjoy a Monday movie outing at Compass Rose Brewery. Check with the venue for the featured film.
Cosmic Chuckles: Weekly Comedy Show
Time: 7–9 p.m.
Location: Flying Saucer Raleigh
Admission: FreeAdd some laughter to the start of the week with the Cosmic Chuckles comedy show at Flying Saucer Raleigh.
Halloween Air Hockey Tournament
Time: Starts at 8 p.m.; air hockey is also listed from 8–10 p.m.
Location: Boxcar Bar and Arcade, Raleigh
Admission: Listed as freeHead to Boxcar for a Halloween air hockey tournament. The supplied schedule includes two overlapping air hockey listings at the same venue, combined here into one entry. Confirm the tournament format and end time with Boxcar.
Open Mic Nights Around the TriangleOpen Mic Night at Steel String Brewery
Time: 6–11 p.m.
Location: Steel String Brewery, Carrboro
Admission: FreeEnjoy an evening of local performances at Steel String Brewery in Carrboro.
Open Mic Night at KōMANA Brewing Company
Time: 7–10 p.m.
Location: KōMANA Brewing Company, Cary
Admission: FreeKōMANA Brewing Company’s open mic night offers another Monday entertainment option in Cary.
Carrboro Open Mic
Time: Starts at 7:30 p.m.
Location: Speakeasy, Carrboro
Admission: FreeCatch Carrboro Open Mic at Speakeasy starting at 7:30 p.m.
Anyone interested in performing should contact the venue for sign-up procedures and available slots.
Explore More Things to Do Around the TriangleMonday’s lineup offers activities throughout the day, from toddler playtime and Halloween storytime to Diwali celebrations and evening entertainment.
Families can explore trunk-or-treat or the Carolina Pines fall carnival, while readers, music fans and comedy lovers have several free outings to choose from.
Follow DoRaleigh.com for daily updates on government meetings, local festivals, and community happenings — your one-stop guide to everything Raleigh!
Connect With Us: Instagram | Facebook | BSky | Linkedin
Share With Us: Post your community News, Events, on our Submissions Page.
Advertise With Us: Interested in Advertising click here.Published by Bryan Tomlinson
Design, Optimization, and Marketing Services Provided by BTDesigns.pro
Event information is based on the supplied listings. Confirm schedules, registration requirements, age policies and promotional terms with organizers before attending. Free admission may not include food, drinks or other purchases.
#ApexEvents #CarrboroEvents #CaryEvents #DiwaliCelebration #DoRaleigh #DurhamEvents #events #FamilyActivities #FreeThingsToDo #HalloweenEvents #MondayEvents #News #October262026 #RaleighEvents #TriangleEvents